LLM Memory Needs Rules for Change, Not Just More Room
A useful memory system must do more than preserve and retrieve old information. When facts change, agents need explicit rules for deciding whether to append, replace, discount, or reconcile what they previously knew.

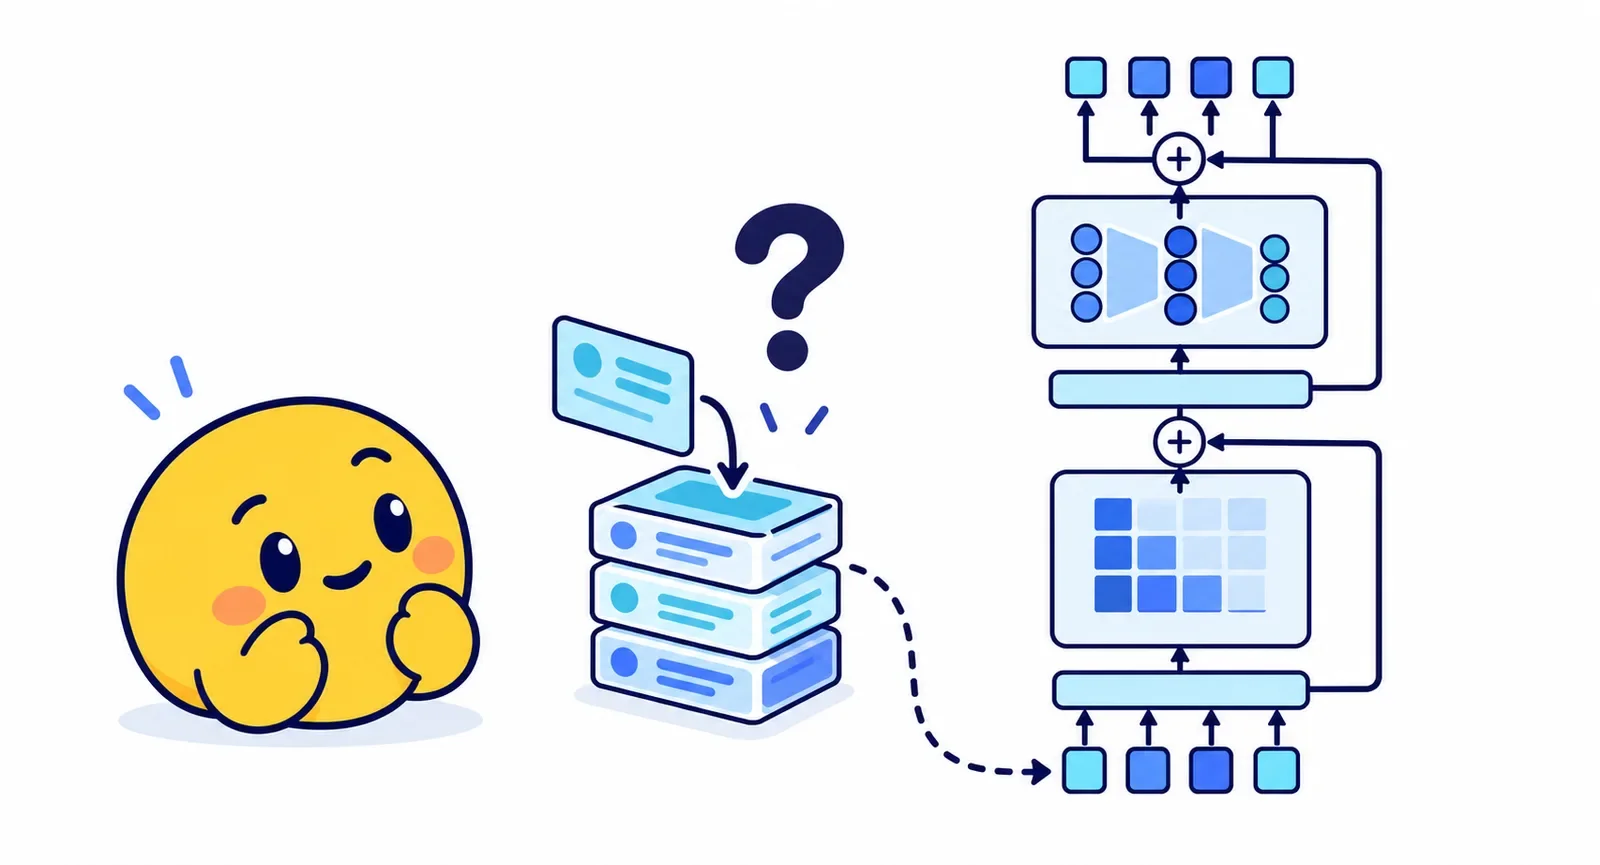
Treat agent memory as state management: define how new evidence supersedes, accumulates, or conflicts with old information, then test those transitions directly.
Long context windows and retrieval systems solve an important problem: they make earlier information available. Availability, however, is not the same as correctness. An agent can retrieve both an obsolete instruction and its replacement, yet still choose the wrong one. The missing capability is a policy for change—what happens to the agent’s working state when new evidence conflicts with what came before.
A community article published on October 15 frames this issue as belief revision, using the term operationally: the system’s current answer or action should change when the relevant evidence changes. It separates the rule that updates memory from the rule that reads it, then uses linear attention and additive associative memory to make those mechanics easier to inspect. The article’s central warning is that simply accumulating associations can preserve contradictory values instead of replacing the outdated one.
That distinction is useful beyond any single model architecture. It gives builders a practical way to ask whether an application merely stores history or can maintain a dependable current state.
A bigger archive does not define the current truth
Consider a coding agent that first learns a function accepts one identifier. Later, the repository changes and the function requires both an organization identifier and a user identifier. Keeping both signatures in a transcript prevents information loss, but it does not tell the agent which call to generate next. Retrieval may even return both snippets because both are highly relevant to the same query.
This reveals three separate jobs that are often bundled together under “memory”:
- Retention preserves observations.
- Selection finds observations relevant to a query.
- Revision determines how newer evidence changes the state used for an answer.
Long context primarily expands retention. Retrieval improves selection. Revision needs extra semantics: recency, authority, confidence, scope, or a targeted update to an internal association. None of those follows automatically from storing more tokens.
The same pattern appears in support assistants, research workflows, and autonomous tools. A shipping address can be replaced, a hypothesis can be weakened, and a deployment target can change. If the system treats every statement as another equally valid fact, its memory becomes a ledger of observations rather than a representation of the present.
Update policy and read policy are different controls
A useful design review should examine writes and reads independently. On the write side, an application might append every record, overwrite a keyed value, decay older state, or store a correction linked to the claim it supersedes. On the read side, it might rank by semantic similarity, filter by effective time, prefer an authoritative source, or ask a model to reconcile conflicts.
Revision can happen in either place. An overwrite-oriented write makes the current value easy to read, but may erase useful history. An append-only store preserves auditability, but forces the reader to resolve versions correctly every time. A hybrid can retain the event log while maintaining a separate materialized view of current state. That familiar database pattern is a strong mental model for agent memory: preserve provenance, but do not make each downstream prompt reconstruct reality from scratch.
The right policy depends on the domain. “Use the new API signature” looks like replacement. “Two sensors reported different temperatures” may call for aggregation. “A user changed preferences for this project only” requires scoped replacement. “An untrusted web page contradicts an administrator rule” should not trigger revision at all.
Why additive memory exposes the problem
Associative memory can be pictured as connecting a key with a value. An additive update strengthens or adds such connections. This is helpful when repeated observations agree: several compatible signals can reinforce an association. It is less suitable when the intended operation is substitution. Adding a new value under a similar key can leave both old and new contributions in the state, producing a mixture at read time. Similar keys can also interfere with one another.
The lesson is not that additive mechanisms are universally defective. Their behavior may be exactly right for accumulating evidence, and learned gates or read-time controls can alter the outcome. Rather, an update should match the meaning of the event. A replacement needs a correction mechanism, not merely one more positive write. The source article points toward prediction-error updates such as the delta rule: compare the memory’s current output with the desired new value, then write the difference.
For product teams, the architectural details matter less than the testable consequence. After a correction, does the system return the new value cleanly, continue to blend versions, or revert when the prompt changes?
A practical evaluation for changing facts
Static recall benchmarks are insufficient because they reward finding information without testing whether it can become obsolete. A compact revision evaluation can use short event sequences with controlled changes:
- establish a fact, query it, replace it, and query again;
- introduce two similar entities and update only one;
- provide a newer but lower-authority claim;
- apply a change within one project or time range, then query outside that scope;
- repeat a correction after a long distractor sequence;
- request both the current value and the historical record.
Score more than final-answer accuracy. Record whether the response cites the governing evidence, whether unrelated associations changed, and whether the old value remains available when history is explicitly requested. Tests should also vary phrasing so success cannot come from copying the newest nearby sentence.
A robust system should distinguish four outcomes: unchanged, accumulated, superseded, and unresolved. When evidence is ambiguous, “unresolved” is often safer than silently overwriting. Exposing that state also lets an application request confirmation instead of manufacturing certainty.
Memory design is policy design
The practical takeaway is that memory capacity is only one dimension of reliability. Builders should document what counts as a key, which sources may revise a claim, how scope and time are represented, whether history is retained, and how conflicts surface to the caller. Those choices are application policy even when a learned model implements part of them.
Long context and retrieval remain valuable, but they should be evaluated as components of a larger state-management system. The important question is no longer only “Can the model find what happened?” It is also “Can the system determine what is true now, and explain why the answer changed?”
Source: The Missing Piece in LLM Memory: Why Long Context and Retrieval Aren't Enough for Belief Revision ↗. How we write