A Smaller Model File Is Only Half the Quantization Story
A September 14 community report on AutoRound offers a useful reminder: matching file sizes does not mean two quantized models preserve the same behaviour.

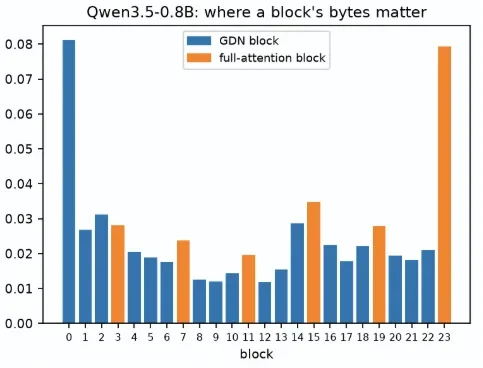
Compare quantized artifacts at a matched resource budget, then test behaviour in the languages and tasks you actually need.
A September 14 community post from FINAL-Bench describes corrections to an AutoRound-based GGUF quantization workflow. The authors report that matching the optimization scheme to the export format, and enabling an additional rounding algorithm, improved their comparisons with reference models. They also describe sensitivity to calibration text and disclose configurations that did not improve results. These are the authors' measurements, not independently reproduced results from this publication.
The useful question raised by this report is broader than one configuration: what does it mean for a compressed model to be good? File size is easy to compare. Behaviour is not. A model can fit into memory and load successfully while still making different mistakes from the original. Treating successful export as successful compression leaves the most important part of the evaluation unfinished.
Separate three decisions
Start by separating storage, execution and quality. Storage concerns the bytes on disk and the space required to distribute them. Execution concerns whether the runtime can use the artifact efficiently on the intended machine. Quality concerns the answers, probabilities or decisions produced after compression. Improvement in one category does not establish improvement in either of the others.
For an illustrative customer-support assistant, a smaller file might allow deployment on an existing workstation. That is a real operational benefit. But if product codes become less reliable or responses in a secondary language deteriorate, the deployment can still be a poor trade. Write those requirements down before looking at a headline compression ratio. Otherwise the easiest number to measure becomes the decision by default.
Compare the artifact that actually ships
A training or tuning log describes an intermediate process. Users run the exported file. Keep the final artifact, its checksum, the converter version and the runtime version together in the evaluation record. If the export step changes how numbers are represented, repeat the relevant measurements after export rather than assuming the intermediate result survives unchanged.
A practical comparison sheet can have one row per artifact and columns for disk size, peak memory, startup time, representative response latency and task scores. Record the same prompt format and generation settings for each row. Where hardware differs, label that difference instead of placing the results in an apparently controlled comparison. The goal is a traceable decision, not a table with the most impressive-looking entry.
Keep calibration and evaluation distinct
Calibration material helps a compression procedure choose how to approximate a model. Evaluation material asks whether those choices work on cases not used to make them. Reusing the same examples for both purposes risks rewarding a configuration for adapting to the examination questions.
Imagine that most customers write short English questions, while a smaller group uses longer Spanish requests containing technical identifiers. A useful evaluation set would represent both groups and inspect failures separately. An aggregate score dominated by the larger group could conceal a regression that makes the smaller group's experience unacceptable. This is a reason to design slices, not a claim that any one language always needs a particular compression setting.
Measure closeness and usefulness
Distributional comparisons can show how far a compressed model moves from a reference. Task evaluations can show whether the resulting changes matter for a particular application. Neither is a complete substitute for the other. A close approximation to a weak reference does not make the application good, while one successful demonstration says little about consistency.
For a document-extraction workload, evaluate whether required fields are present, whether values match the document and whether the output follows the requested structure. Preserve failure examples alongside the aggregate results. A reviewer should be able to tell whether the compressed model merely phrases an answer differently or changes a value that another system will act on.
The final decision should include a fallback. Keep the last accepted artifact available, record why the replacement was approved and define a small regression set that runs when conversion tools change. Quantization then becomes a repeatable engineering decision: conserve resources while demonstrating that the behaviour needed by users remains acceptable.
Source: Same bytes, closer to the original: two lines of AutoRound we had wrong ↗. How we write