LitPivot Turns Literature Review Into an Editable Part of Research Ideation
Ai2's LitPivot organizes papers around the problem, contribution, or evaluation being revised, then links critiques and suggested changes to researcher-selected evidence.

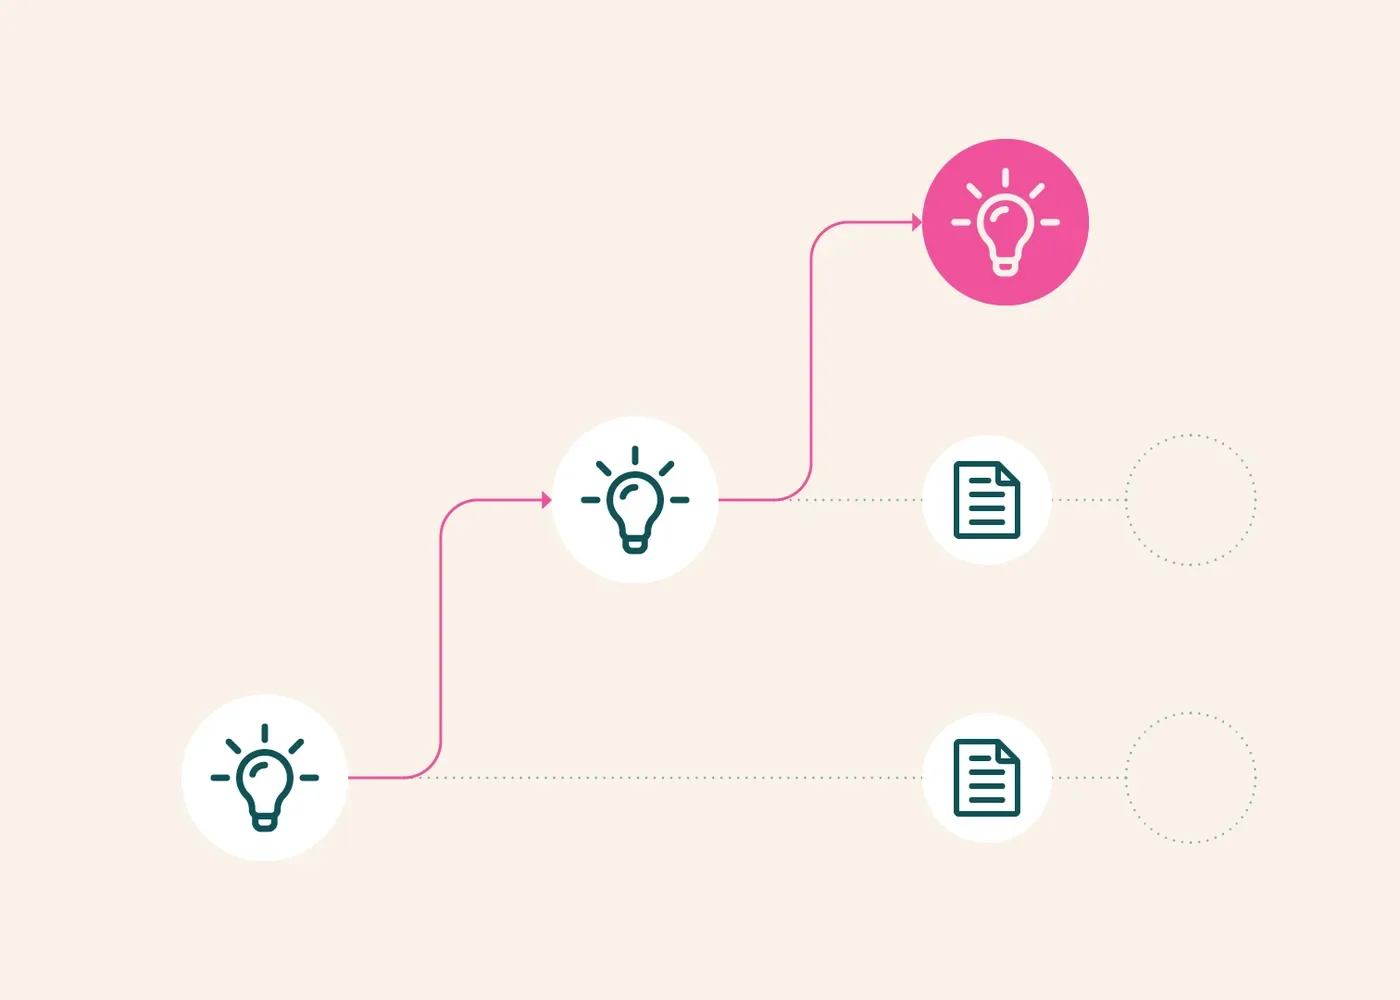
LitPivot's strongest idea is a researcher-controlled revision loop in which evidence selection, critique, and proposal changes remain visibly connected.
Research tools often treat literature search and idea development as separate jobs. A researcher searches, reads, and takes notes, then returns to a proposal and tries to remember which evidence should change which claim. LitPivot, developed by Ai2 with University of Pennsylvania collaborators, explores a tighter loop: select part of an idea, inspect literature organized for that part, request an evidence-backed critique, revise, and then reconsider which papers remain relevant.
The important design choice is not simply adding an AI assistant to an editor. LitPivot makes the relationship between a proposal and its evidence editable. Researchers decide which papers should be used in an assessment and can accept, modify, or reject suggested revisions. That structure offers a useful model for research-support systems even where an automated suggestion should never be treated as a verdict.
A proposal becomes three linked questions
LitPivot segments a short research proposal into a problem, a proposed contribution, and an evaluation plan. Selecting one of these facets changes how related papers are grouped and ranked. For a problem statement, the useful evidence concerns whether the problem exists and why it matters. For a contribution, the key comparison is what prior studies already cover and what gaps they leave. For an evaluation, the question becomes whether the proposed tests address the research question and how neighboring work has tested similar claims.
This decomposition matters because “find related work” is too broad to guide a revision. A paper can be highly relevant to the application area yet say little about the novelty of a method. Another can supply an evaluation precedent without supporting the problem framing. Facet-specific retrieval gives the researcher a reason for viewing each cluster rather than presenting one undifferentiated relevance list.
After the researcher chooses papers, the system produces a critique and suggested rewrite accompanied by excerpts. Revising one facet can also trigger warnings that another may now be stale. A narrower contribution, for example, may require a different evaluation. Literature is reranked after edits, turning retrieval into a recurring step rather than a search performed once at the start.
What the reported studies establish
The team first analyzed notes from four completed computer-science projects and identified 21 changes in direction prompted by literature. It characterized these as either differentiating an idea from existing work or aligning it with existing work. A formative study with five researchers then informed the interface.
In a subsequent lab study, 17 researchers each developed one assigned idea with LitPivot and another with a baseline combining a text editor and an AI question-answering tool. Both conditions used the same paper collection. Two domain experts, blinded to the tool used, rated how well the resulting proposals employed relevant literature to justify the idea. The LitPivot proposals received higher ratings. Participants also reported stronger understanding of the literature and greater improvement in novelty and usefulness.
A follow-up involved five researchers using LitPivot on their own projects in 30-minute sessions. Some vetted new ideas; others refined mature framing. These results support further investigation, but they do not establish that the workflow improves eventual scientific outcomes, works equally well across disciplines, or remains helpful during long projects. The samples were small, and some outcomes were self-reported. The comparison also isolates a structured workflow against a particular baseline, not against every expert review practice or literature tool.
The real control surface is evidence selection
Evidence-linked output is only as sound as the evidence set. LitPivot usefully leaves paper selection with the researcher, but that also preserves familiar review risks: narrow queries, missing terminology, publication bias, weak studies, or an overrepresented subfield. A supporting excerpt can show where a suggestion came from without proving that the underlying claim is correct or representative.
Researchers evaluating this pattern should therefore inspect more than the fluency of proposed rewrites. Useful questions include whether retrieval exposes competing findings; whether exclusions are visible; whether an excerpt retains enough context to interpret it; whether rankings can be challenged; and whether the system distinguishes absence of retrieved evidence from evidence of absence. Version history also matters, because a proposal may appear well grounded after its earlier alternatives and discarded evidence have disappeared from view.
A practical review can use a simple trace for each major change: original claim, selected papers, relevant passages, critique, revision, and the researcher's reason for accepting it. That record makes it easier for a collaborator to detect an unsupported leap. Teams can also deliberately run separate searches for the problem, mechanism, competing approaches, and evaluation, then compare the overlap rather than trusting a single ranking.
Where the workflow can help
LitPivot is best understood as a deliberation aid for moments when reading should change a proposal. It can make hidden dependencies visible: a contribution may no longer be novel under one literature cluster, or an evaluation may test the old version of a claim. The system's value lies in keeping those tensions close to the text and giving researchers explicit choices about evidence and revisions.
That is different from automating novelty judgment. Novelty depends on coverage, interpretation, timing, and disciplinary context. A well-designed assistant can help researchers articulate why an idea differs and identify what must be checked, while the researcher remains responsible for search breadth, source quality, and the final claim. LitPivot's lasting contribution may be this interaction model: literature is not a static bibliography appended after ideation, but a changing constraint that participates in the idea's development.
Source: LitPivot: Developing research ideas through dynamic contextualization within the literature landscape ↗. How we write