LeRobot’s Humanoid Stack Separates Intent From Balance
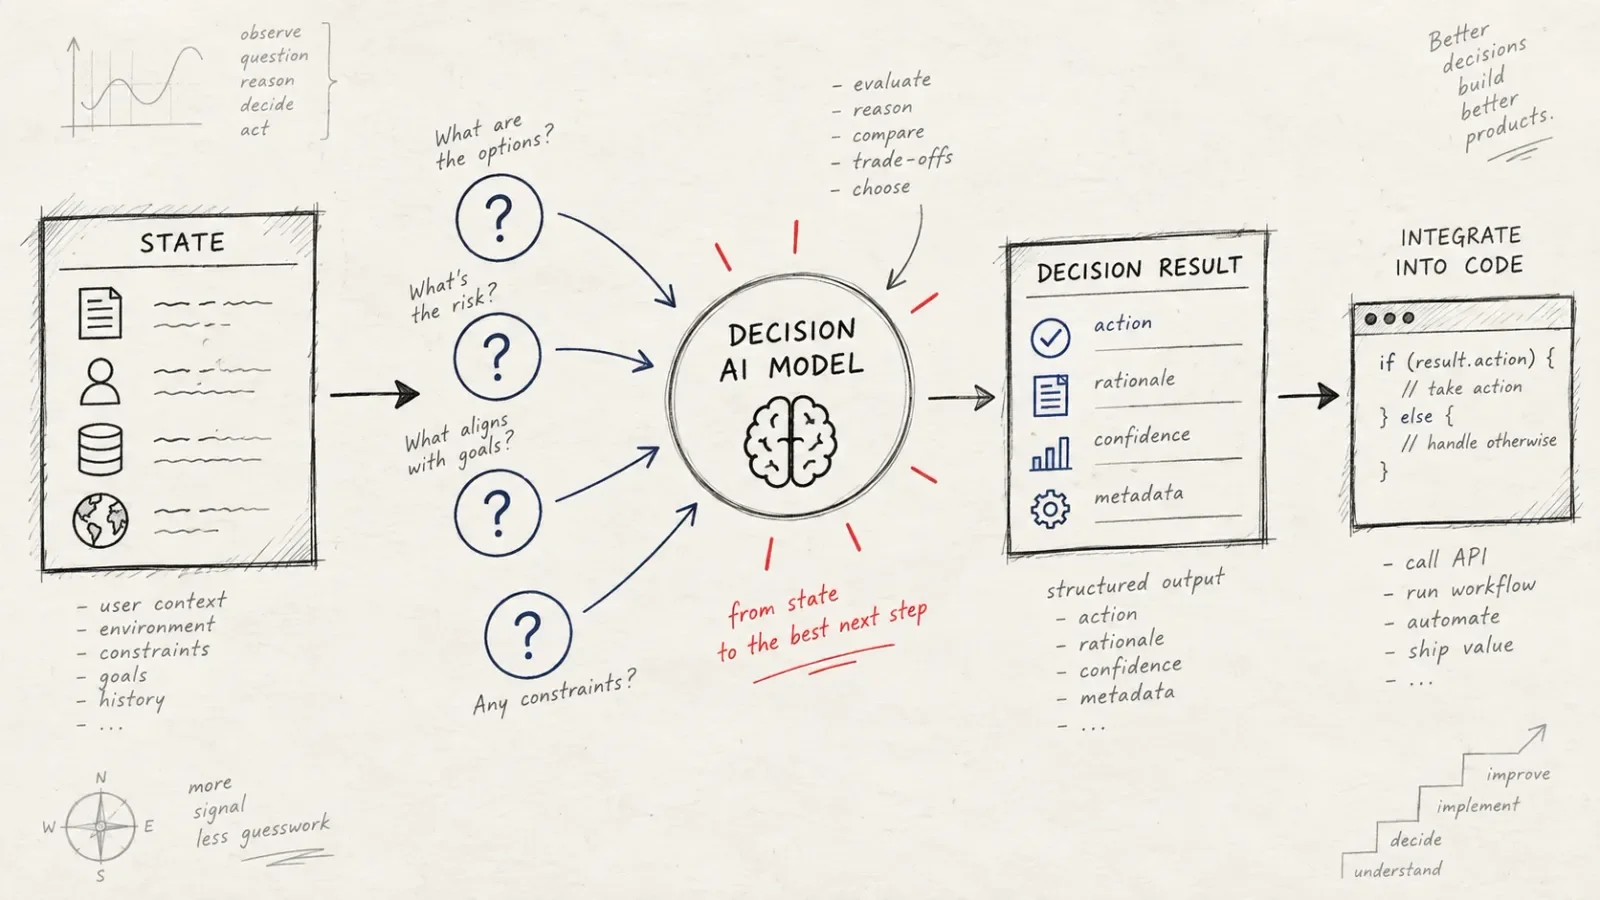
A new Unitree G1 workflow in LeRobot uses learned motion tokens and a fast whole-body controller, illustrating why humanoid policies benefit from a layered control stack.
 Article·5 min
What’s new, what matters, and what to build next.
A new Unitree G1 workflow in LeRobot uses learned motion tokens and a fast whole-body controller, illustrating why humanoid policies benefit from a layered control stack.
Article·5 minA practical method for narrowing a crowded field of agent frameworks and harnesses by testing permissions, recovery, observability, cost, and operational fit on one representative task.
Article·6 minLeRobot's LanceDB integration turns one robotics dataset into a remote training source, search index, and curation workspace. The important shift is not just faster loading, but a simpler path from inspecting failures to defining the next training set.
Article·6 minLiquid AI's compact draft model accelerates token generation for LFM2.5-VL-3B, but its real value depends on how much of a vision-language workload is spent decoding rather than processing images and prompts.
Article·5 minNVIDIA’s Warp and MuJoCo Warp can batch compatible robot simulations on a GPU. The important engineering work is preserving task behavior, sizing resources, and measuring throughput without confusing queue time for completed physics.
Article·6 minNVIDIA’s 100M-parameter Nemotron 3 Diarization model supports offline and streaming processing for as many as eight speakers. Its release also shows why teams must evaluate attribution, latency and transcription as separate concerns.
Article·5 minJev turns bounded questions about text or structured state into typed signals. The harder engineering work is defining answer spaces, evaluation sets, escalation rules, and application-owned safeguards around those signals.
Article·6 minNative GGUF loading brings compact local checkpoints into familiar Transformers workflows, but hardware, kernel, architecture, and memory constraints still determine whether the packed path is the right choice.
Article·6 minoMLX maintainer Jun Kim is joining Hugging Face while continuing to lead the Apache-2.0 project. The move matters less as a change of ownership than as a test of how sustained maintenance can strengthen the wider MLX ecosystem.
Article·6 minHugging Face's Tokenizers v1 release candidate keeps token IDs and familiar APIs stable while rebuilding key Rust internals for faster encoding, better multicore scaling, and leaner inference-only deployments.
Article·6 minExplore releases and guides from 2024 onward. Dates refer to the original announcements; each article also shows when our coverage was published. How we cover the ecosystem ↗