A proposed Tokenizers optimization accelerates BERT-style normalization by fast-pathing ASCII, caching Unicode decisions, and delaying allocation—while highlighting why performance varies by script and input size.
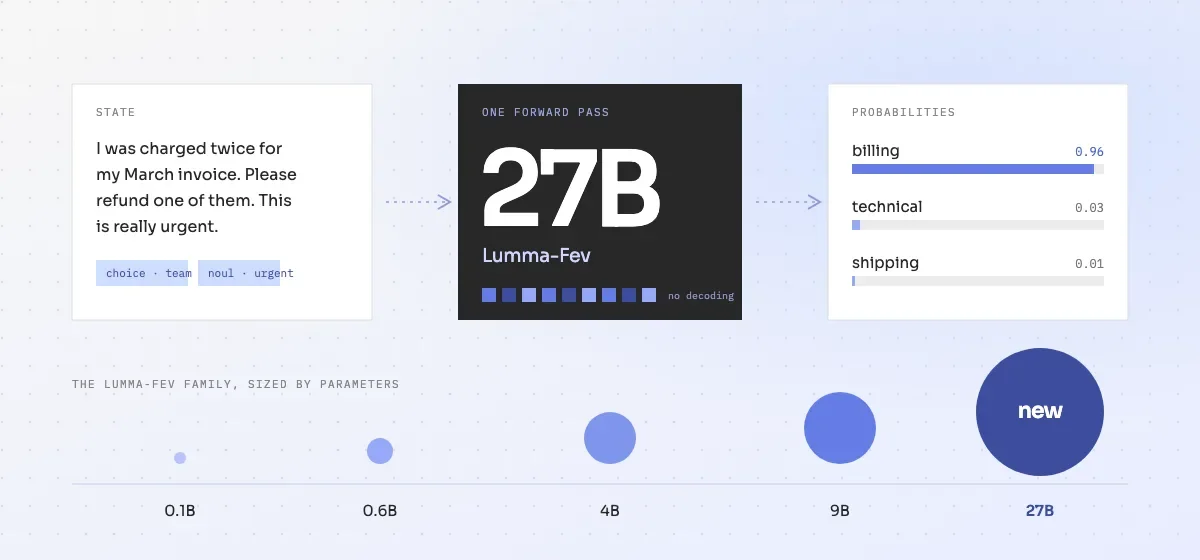
FrontiersMind’s 27B-parameter decision model returns choices and probabilities instead of generated labels. Here is how to assess its calibration, task fit, multilingual limits, and infrastructure cost before using it in an automated workflow.
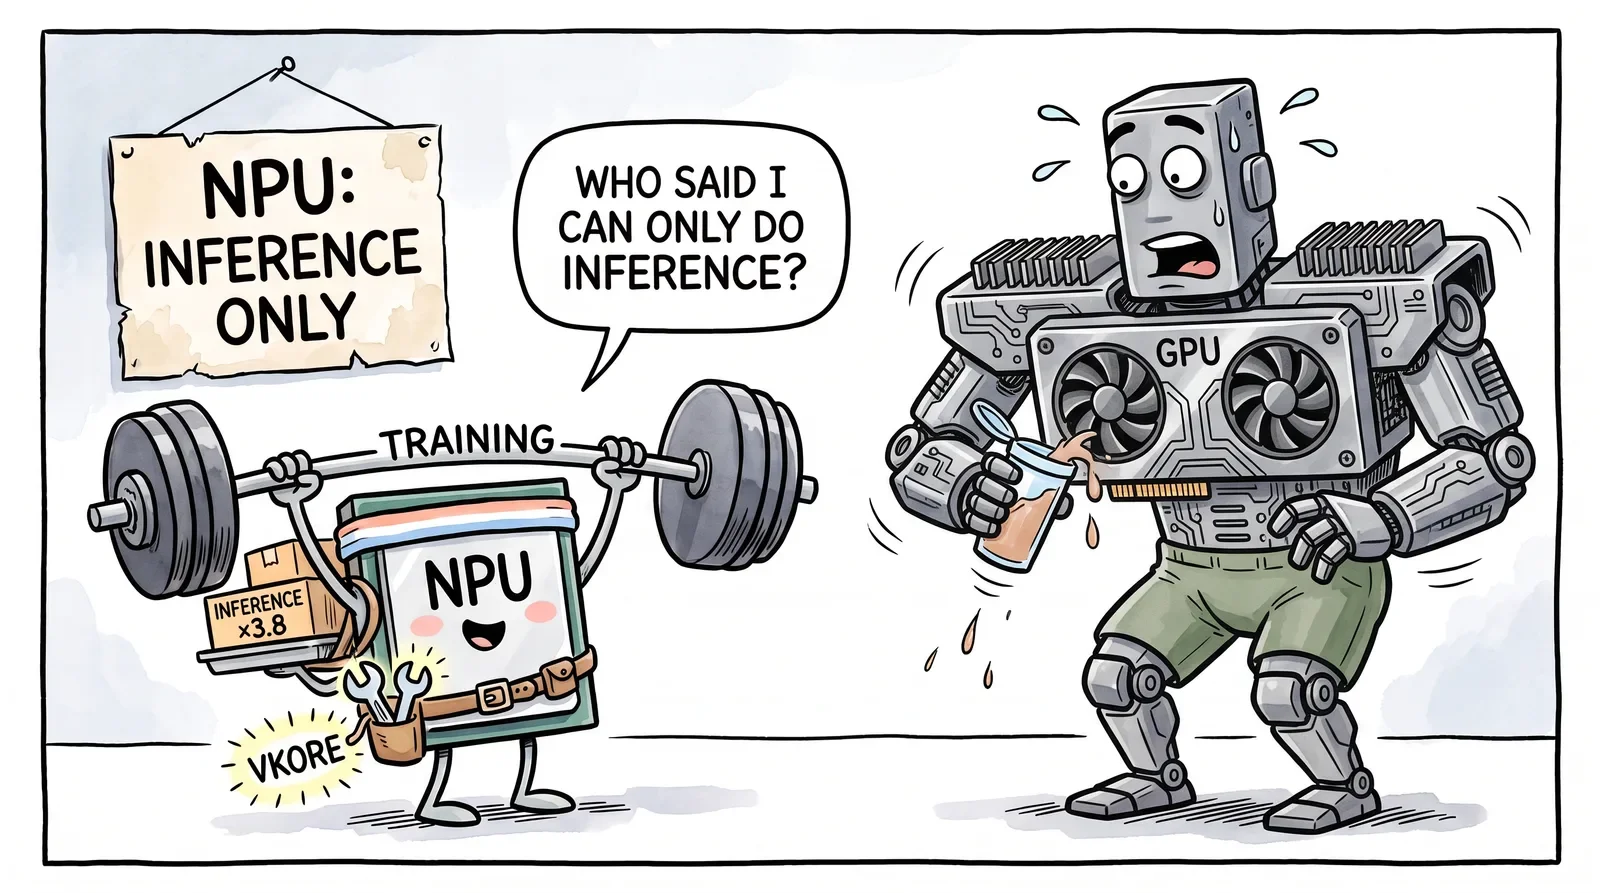
VKORE-46M-NPU turns an unusual hardware claim into a useful evaluation case: can an inference-oriented accelerator execute a complete training loop, and what evidence is needed before that result generalizes?
NVIDIA’s air-traffic-control study offers a useful blueprint for adapting speech recognition without losing sight of data roles, general-language retention, and honest checkpoint selection.
ColGrep-Agent-2B moves repository exploration to a small local model. Its reported benchmark highlights a useful design pattern—and the accuracy, latency and evaluation questions teams should examine before adopting it.
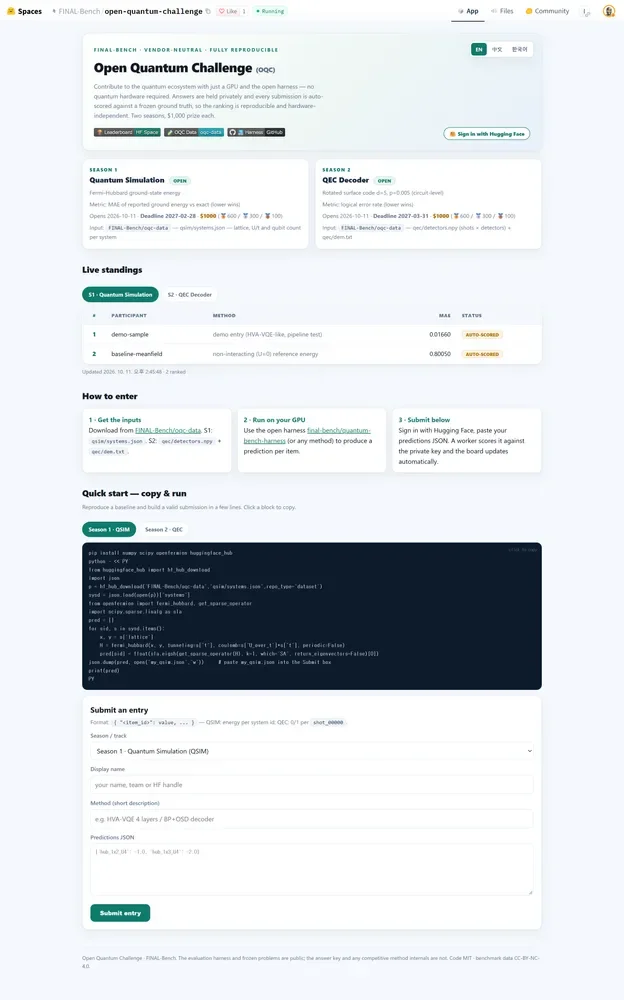
FINAL-Bench's Open Quantum Challenge turns quantum simulation and error-correction decoding into two public GPU tasks. The format highlights how fixed targets and shared harnesses can make specialized research easier to compare, reproduce, and enter.
Ai2 replaced cost-free priority labels with time budgets, hierarchical fair share, and bounded preemption. The design offers a practical lesson: scarce accelerator capacity is easier to govern when policy, accounting, and runtime guarantees are explicit.
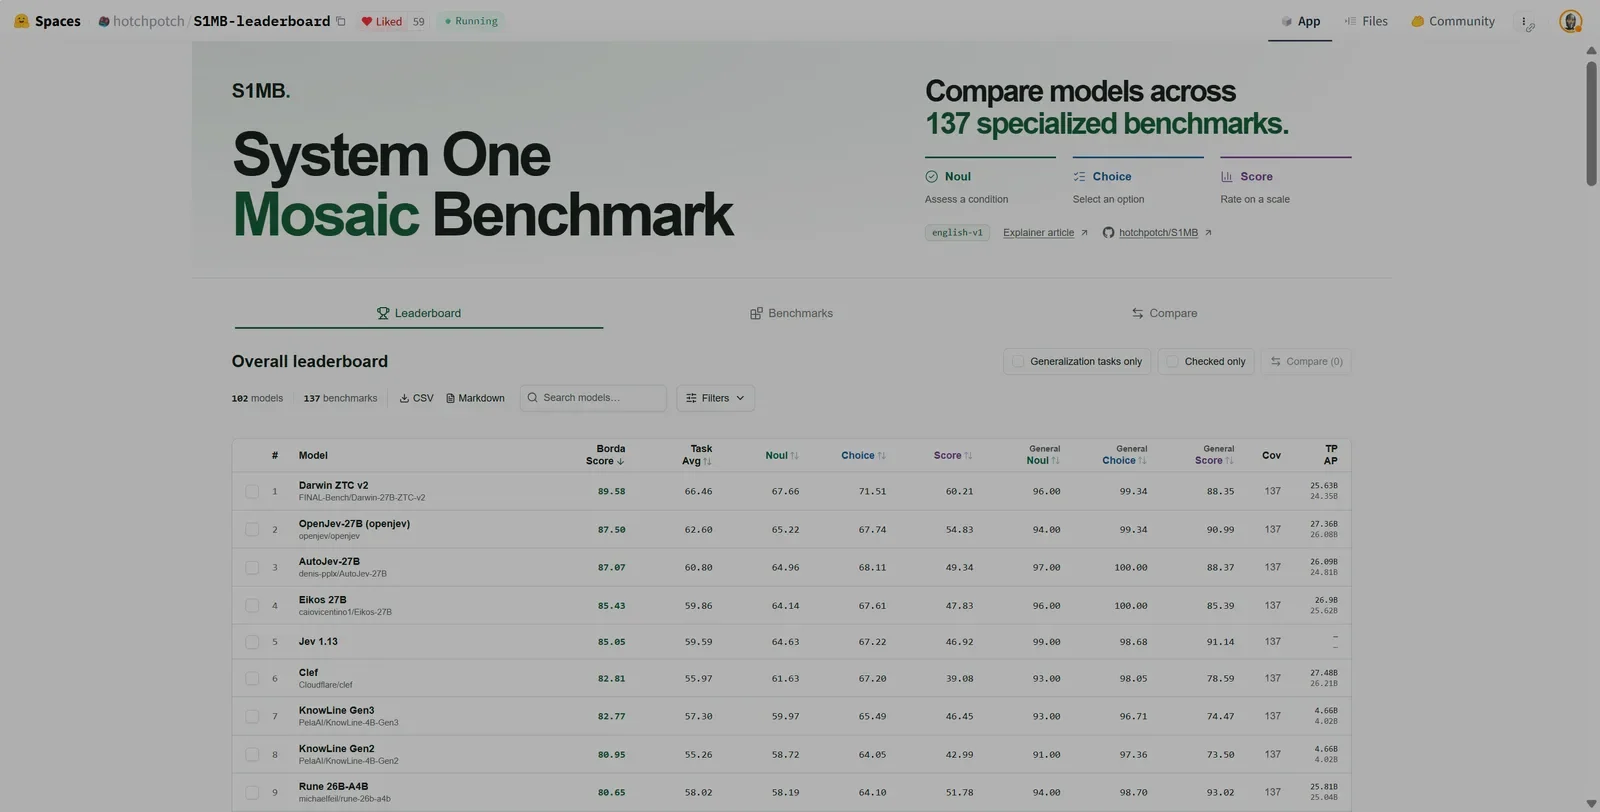
Darwin-27B-ZTC-v2 leads a benchmark for typed, single-pass decisions. Here is how to interpret that result, where rank aggregation helps, and what teams should test before adopting an AI judge.
Hunmin-CUA offers a useful case study in transferring computer-use behavior while tracking what a specialized checkpoint might damage. The broader lesson is to treat preservation metrics, evaluation configuration, and stopping rules as first-class parts of post-training.
ML Intern turns a model idea into a budgeted training workflow. The valuable lesson is not full automation, but a disciplined brief: establish a baseline, run a smoke test, define acceptance criteria, and preserve evidence for review.
Article·6 min
Explore releases and guides from 2024 onward. Dates refer to the original announcements; each article also shows when our coverage was published. How we cover the ecosystem ↗
 Article·6 min