Ai2's open-weight AstaBrief turns retrieved research excerpts into cited reports. Its training recipe highlights a practical lesson for scientific AI: attribution quality depends as much on data selection and claim scope as on model size.
llama.cpp now exposes decision models through a System One-compatible endpoint. Their constrained outputs can simplify routing and validation, but probabilities still require task-specific calibration and fallbacks.
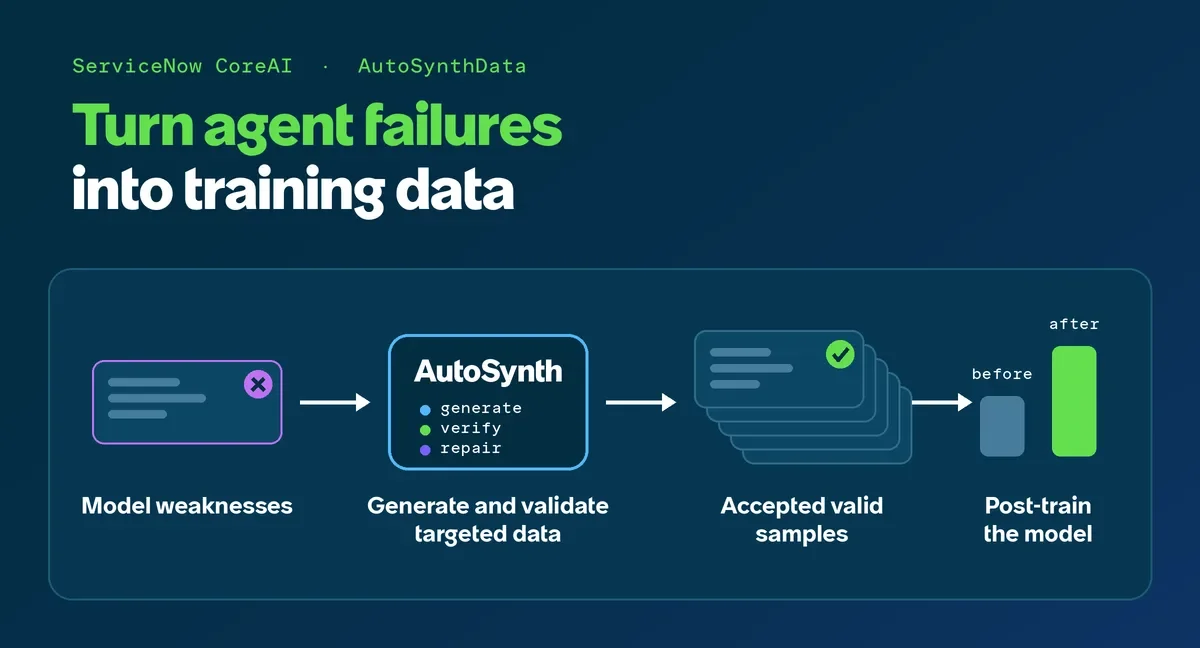
AutoSynthData turns observed agent failures into validated training tasks. Its larger lesson is that synthetic data quality depends on executable environments, discriminating verifiers, controlled variation, and a curriculum that moves as the model improves.
Ai2's redesigned open training stack keeps experts resident on GPUs, adds several forms of parallelism, and exposes the practical tradeoffs behind scaling sparse mixture-of-experts models.
The Open TTS Leaderboard brings reproducible multilingual, voice-cloning, and latency measurements to open text-to-speech models. Its real value is not a universal winner, but a structured way to build a shortlist for a specific product and then validate it with listening tests.
A preview decision-oriented API highlights a useful architecture for routing, triage, and agent control. The real engineering work lies in defining answer spaces, measuring abstention, and keeping authorization outside the model.
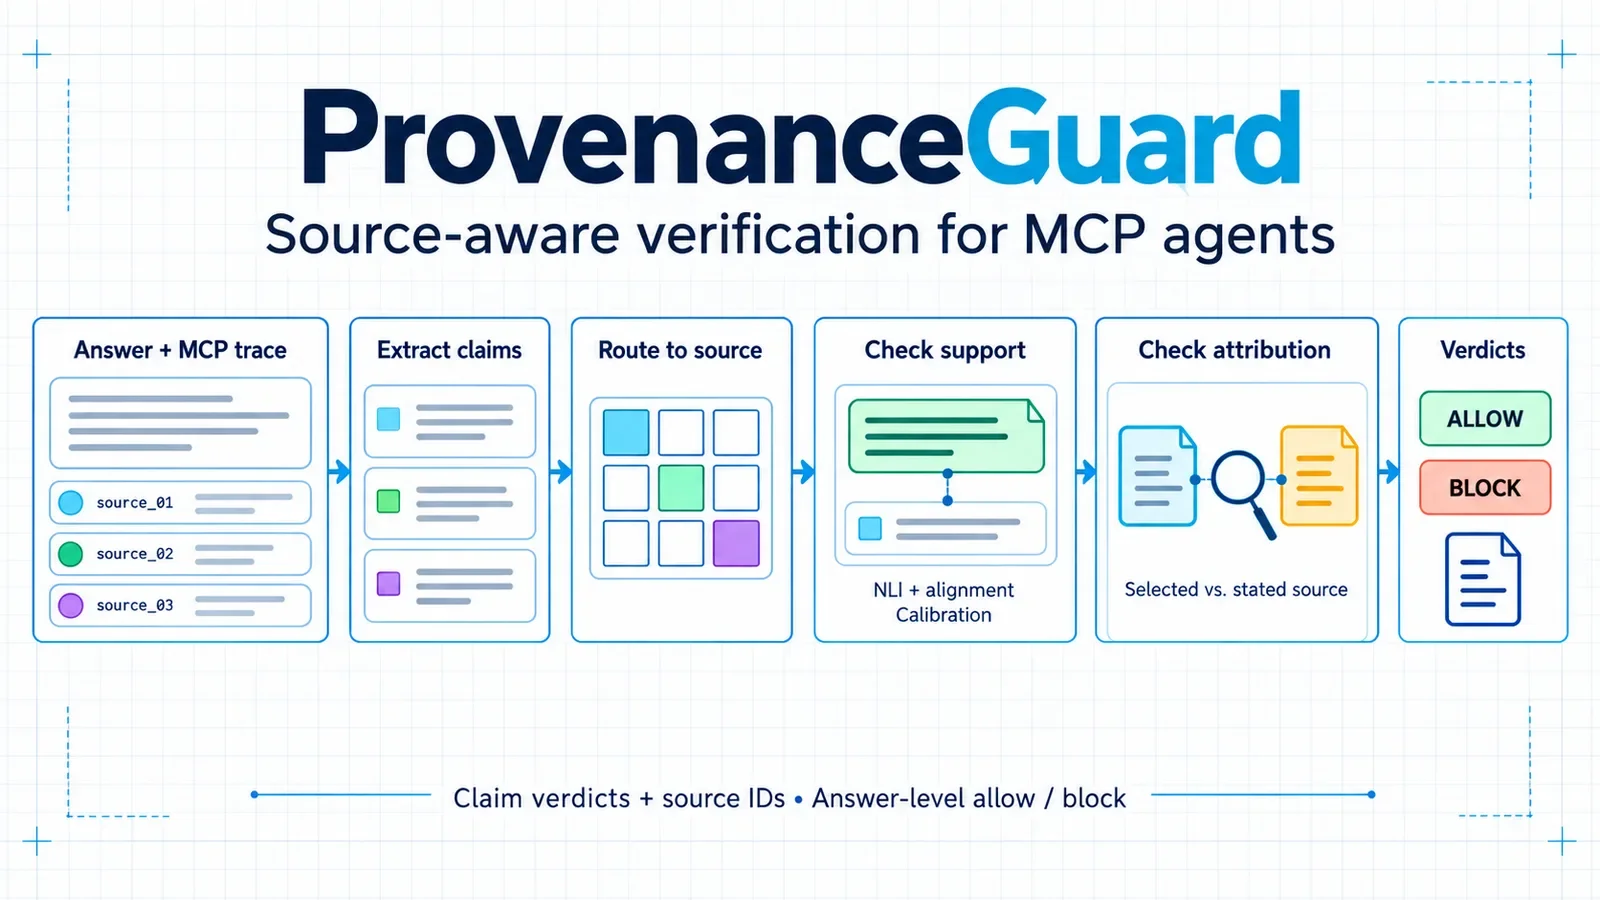
ProvenanceGuard evaluates whether each claim is supported by the source an agent attributes it to. The research also offers a practical blueprint for testing source-aware verification without confusing a conservative gate with proof of correctness.
NVIDIA's Kumo Tabular brings pretrained, in-context prediction to numerical and categorical tables. The more important question is how teams should compare its fast-start workflow with tuned tree models under realistic validation.
The Open Superconductor Challenge invites participants to rank 2D materials with lightweight methods, while reserving expensive many-body computation for verification. Here is how to interpret the task, compare approaches, and avoid mistaking a screening score for a discovery.
ProjectSim argues that robotics evaluation should connect observed failures to targeted training data. The practical challenge is designing benchmarks that separate perception, control, recovery, and real-world robustness while keeping simulation honest.
Article·6 min
Explore releases and guides from 2024 onward. Dates refer to the original announcements; each article also shows when our coverage was published. How we cover the ecosystem ↗
 Article·6 min