A 139M-parameter community model trained on 100 billion tokens offers a useful case study in judging small-model efficiency without confusing benchmark proximity with broad capability.
A September 14 community report on AutoRound offers a useful reminder: matching file sizes does not mean two quantized models preserve the same behaviour.
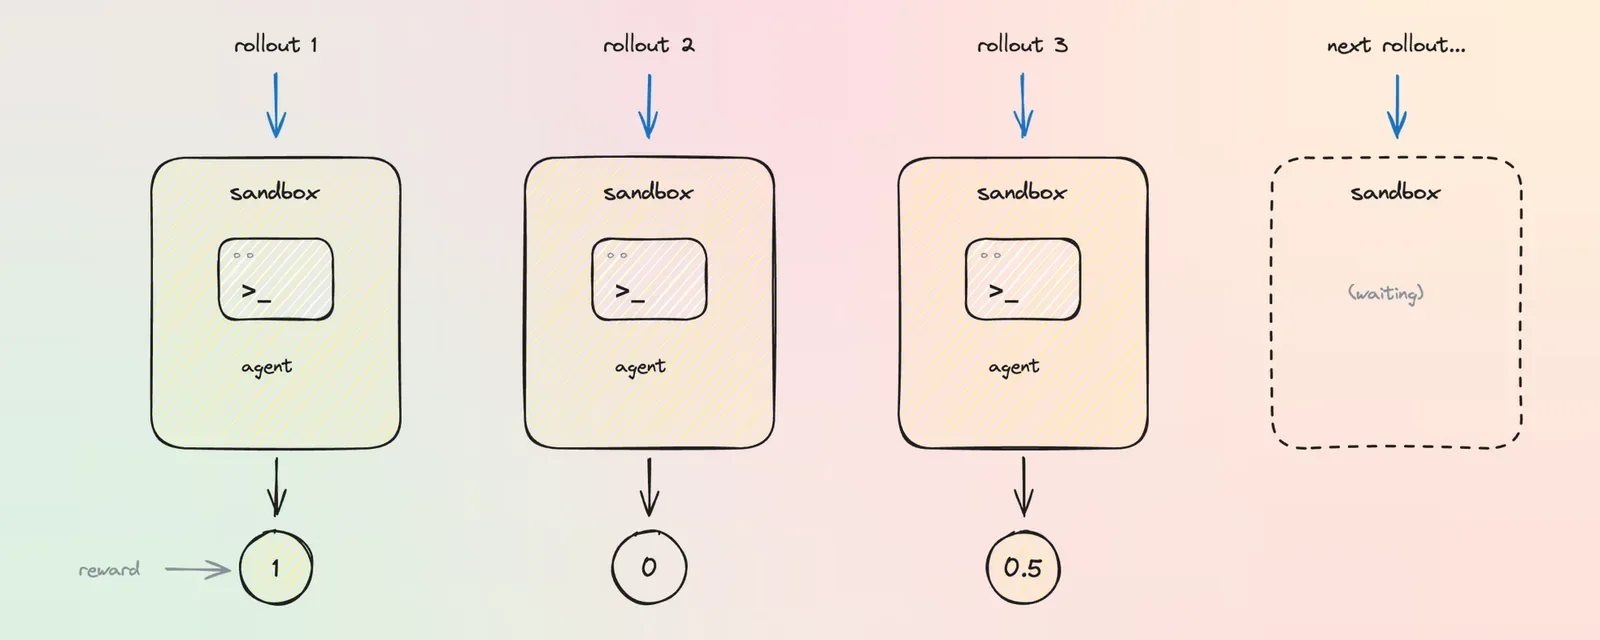
A recent Hugging Face community survey puts the execution environment at the centre of agent training. Here is how to reason about isolation, reset behaviour and reliable rewards.
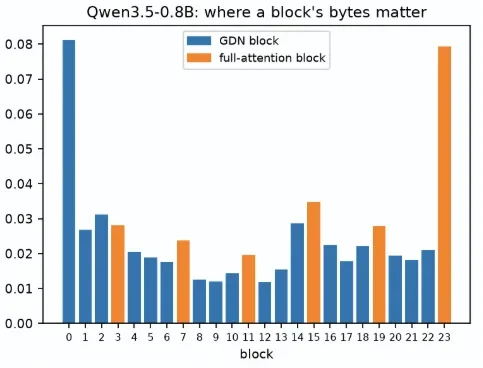
Bartowski’s September 10 experiments explore tensor-specific precision choices. The practical lesson is to compare allocation strategies at a matched memory budget and validate on your workload.
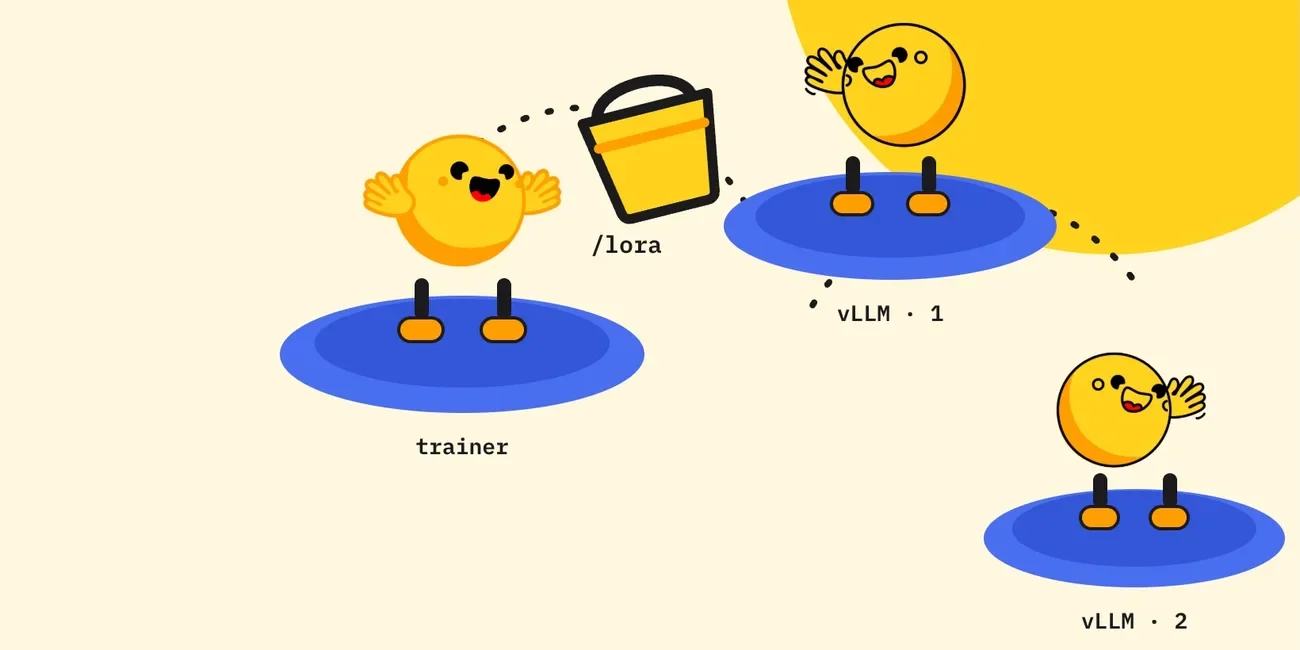
A new AsyncGRPO workflow separates training from rollout generation by moving compact LoRA adapters through shared storage. The design shows how versioning, cache-aware routing, and explicit consistency rules can replace assumptions built into a tightly coupled cluster.
A September community tutorial builds a small collection of Hugging Face repository metadata. The useful ideas extend beyond the example: preserve raw responses, distinguish missing values and record collection boundaries.
A community account of training TinyDiT highlights the choices that matter before a long run begins: image-caption agreement, evaluation prompts and honest boundaries around pretrained components.
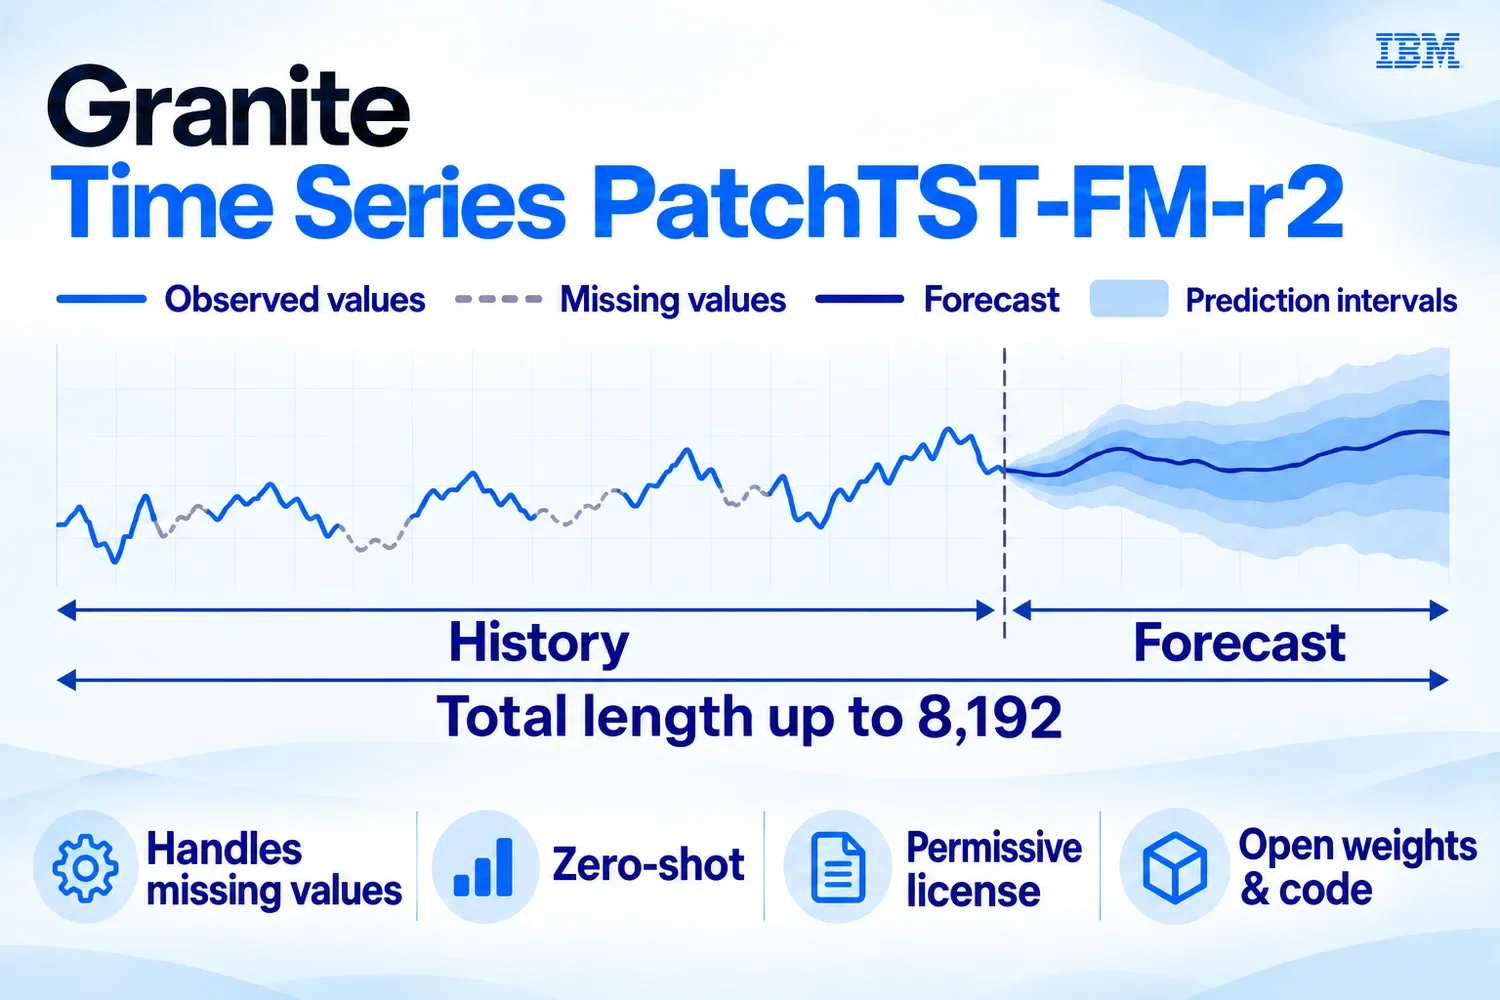
IBM’s latest time-series release makes a useful starting point for discussing uncertainty, honest backtests and the difference between benchmark performance and operational value.
Hugging Face and Earthmover’s September guide addresses the practical work around weather inference. Here is how to evaluate the complete pipeline, from initial conditions to a useful forecast.
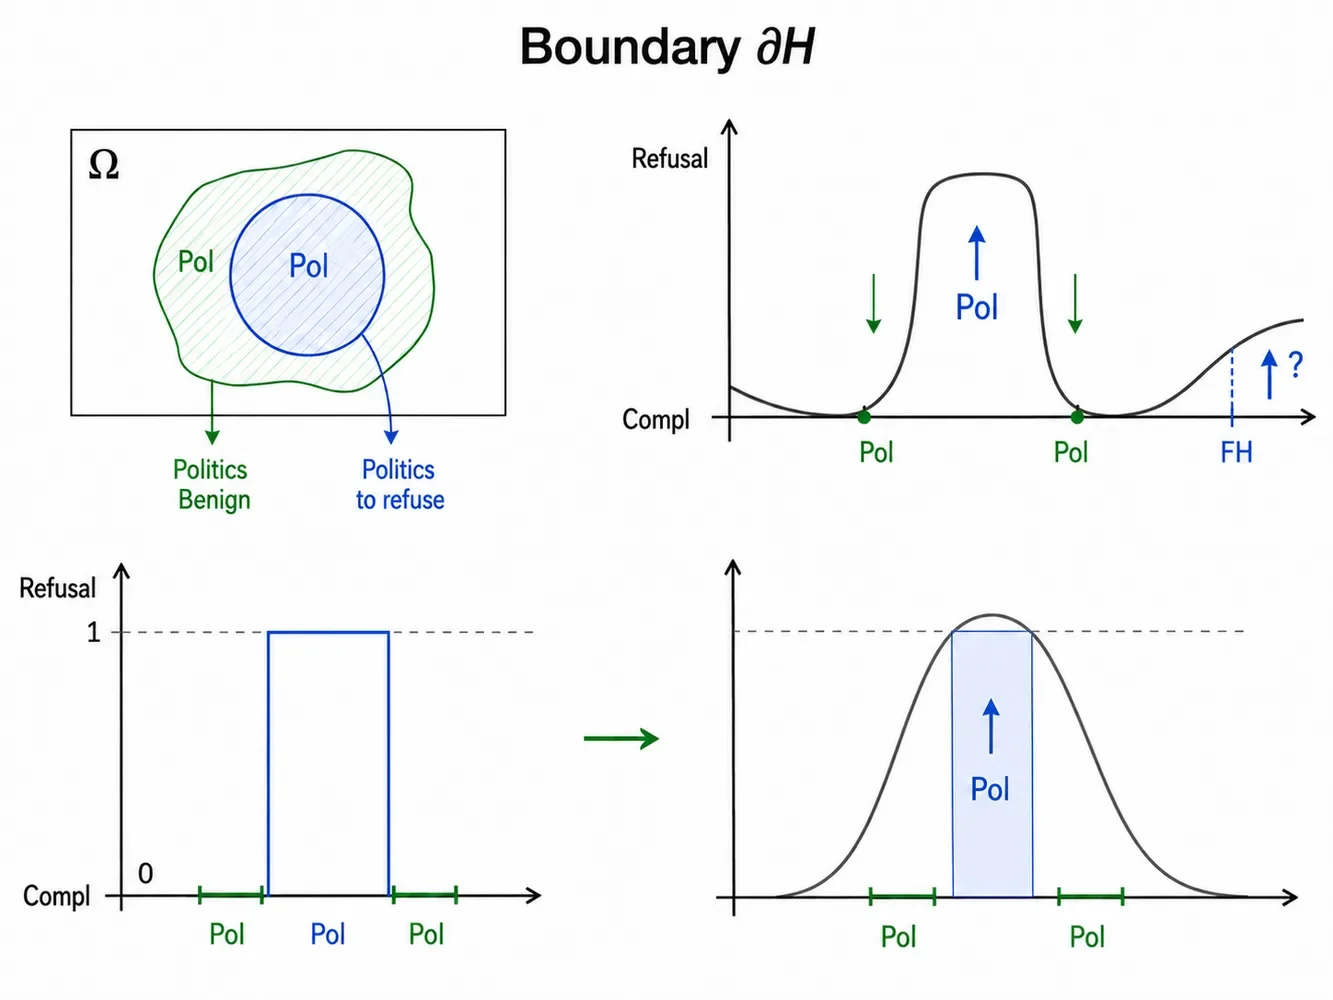
A new boundary-aware safety study highlights a familiar deployment problem: stopping harmful requests without also blocking the legitimate work an assistant exists to do.
Article·5 min
Explore releases and guides from 2024 onward. Dates refer to the original announcements; each article also shows when our coverage was published. How we cover the ecosystem ↗
 Article·6 min